Skip to content

gpu: portable shader nodes, shader library, IBL, GPU skinning, instancing, post passes - #6232

Merged
shai-almog merged 36 commits into
masterfrom
gpu-shader-nodes
Nov 15, 2026
Merged

shai-almog merged 36 commits into
masterfrom
gpu-shader-nodes

Conversation

@shai-almog

Copy link
Copy Markdown
Collaborator

Codename One scenes can now be written with their own shaders, and they render the same way on every backend: Android, iOS Metal, JavaSE GL, HTML5, Linux and Windows.

What's new

  • Portable shader nodes (com.codename1.gpu.shader): a typed expression graph printed to GLSL, Metal and HLSL. ShaderMaterial hooks (base colour, normal, roughness, emissive, vertex offset, discard and more) slot into the built-in lit PBR path, so fog, shadows and tone mapping keep working.
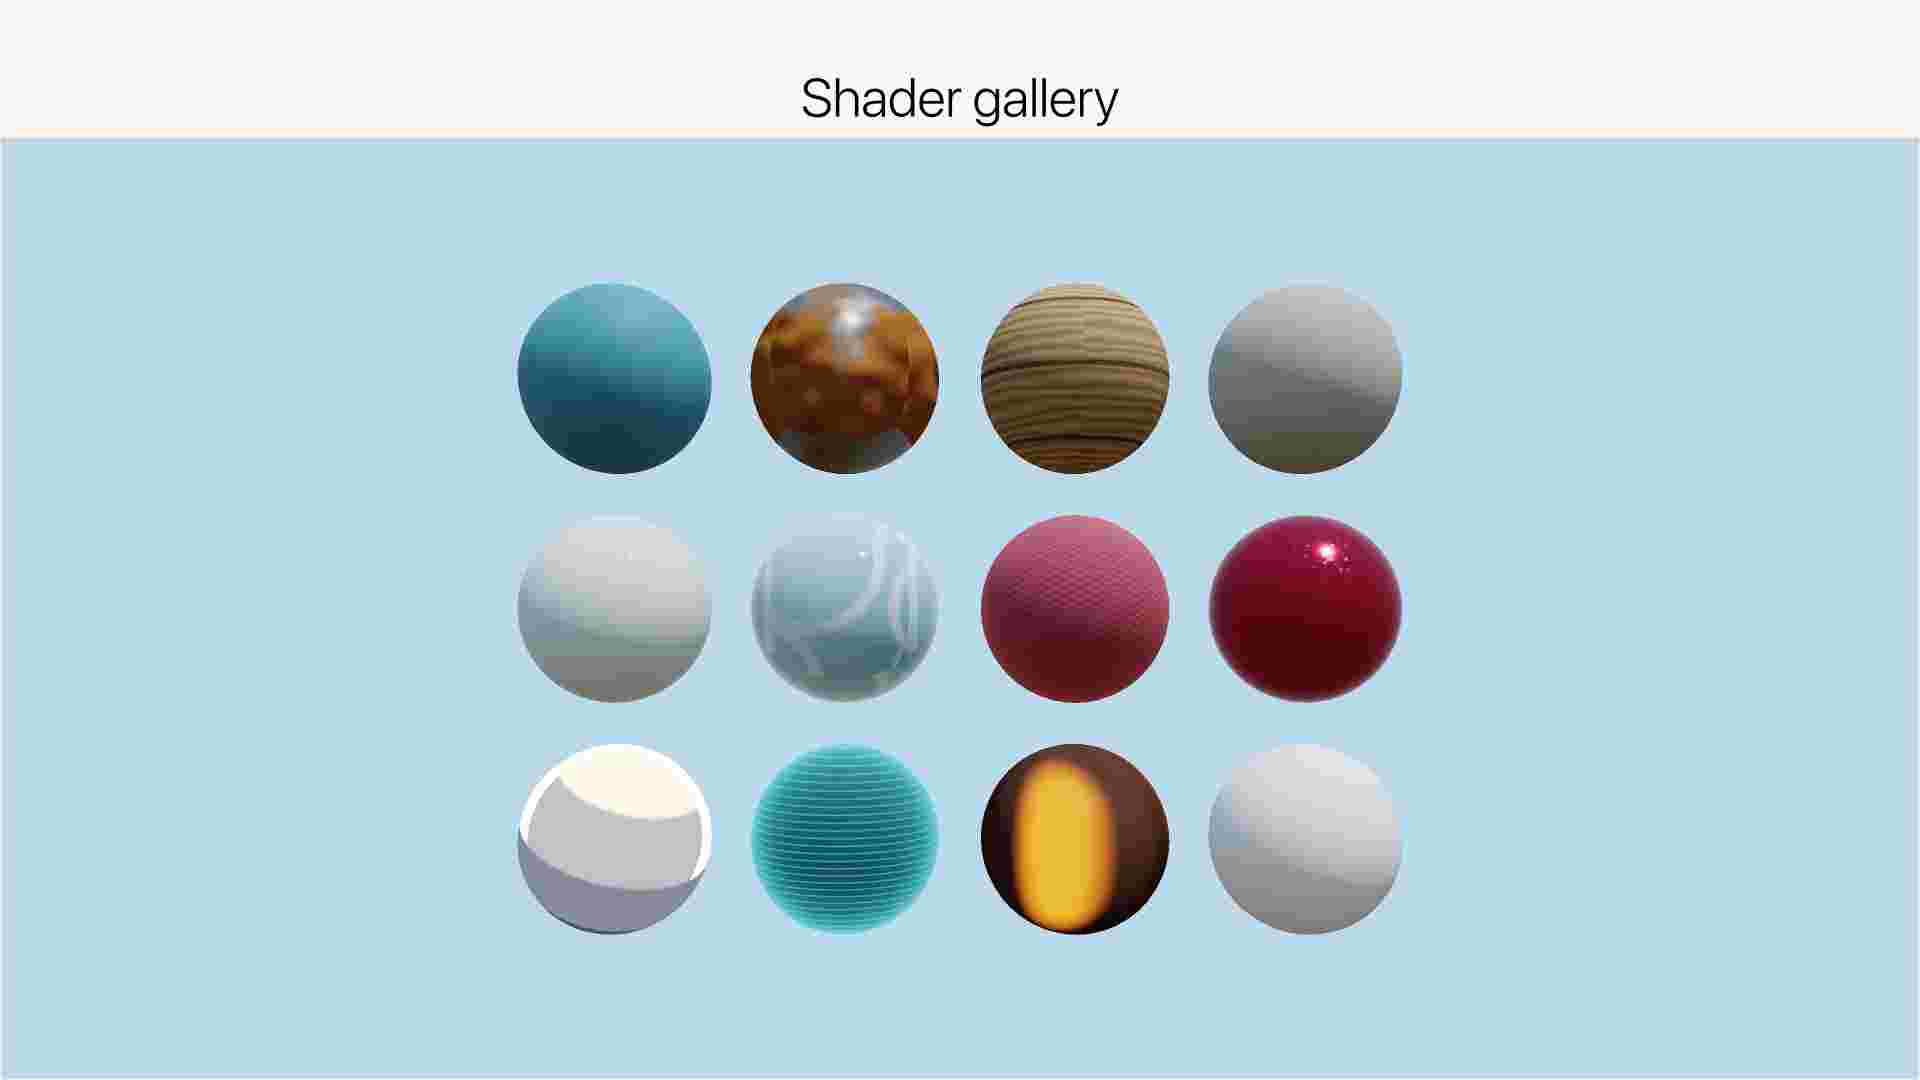
  • Shader library (com.codename1.gpu.shaders): water, terrain, foliage, surfaces, toon, FX, liquids and sky, plus ScenePresets.
  • Engine features:
    • image based lighting
    • normal and detail maps with tangents
    • soft shadows
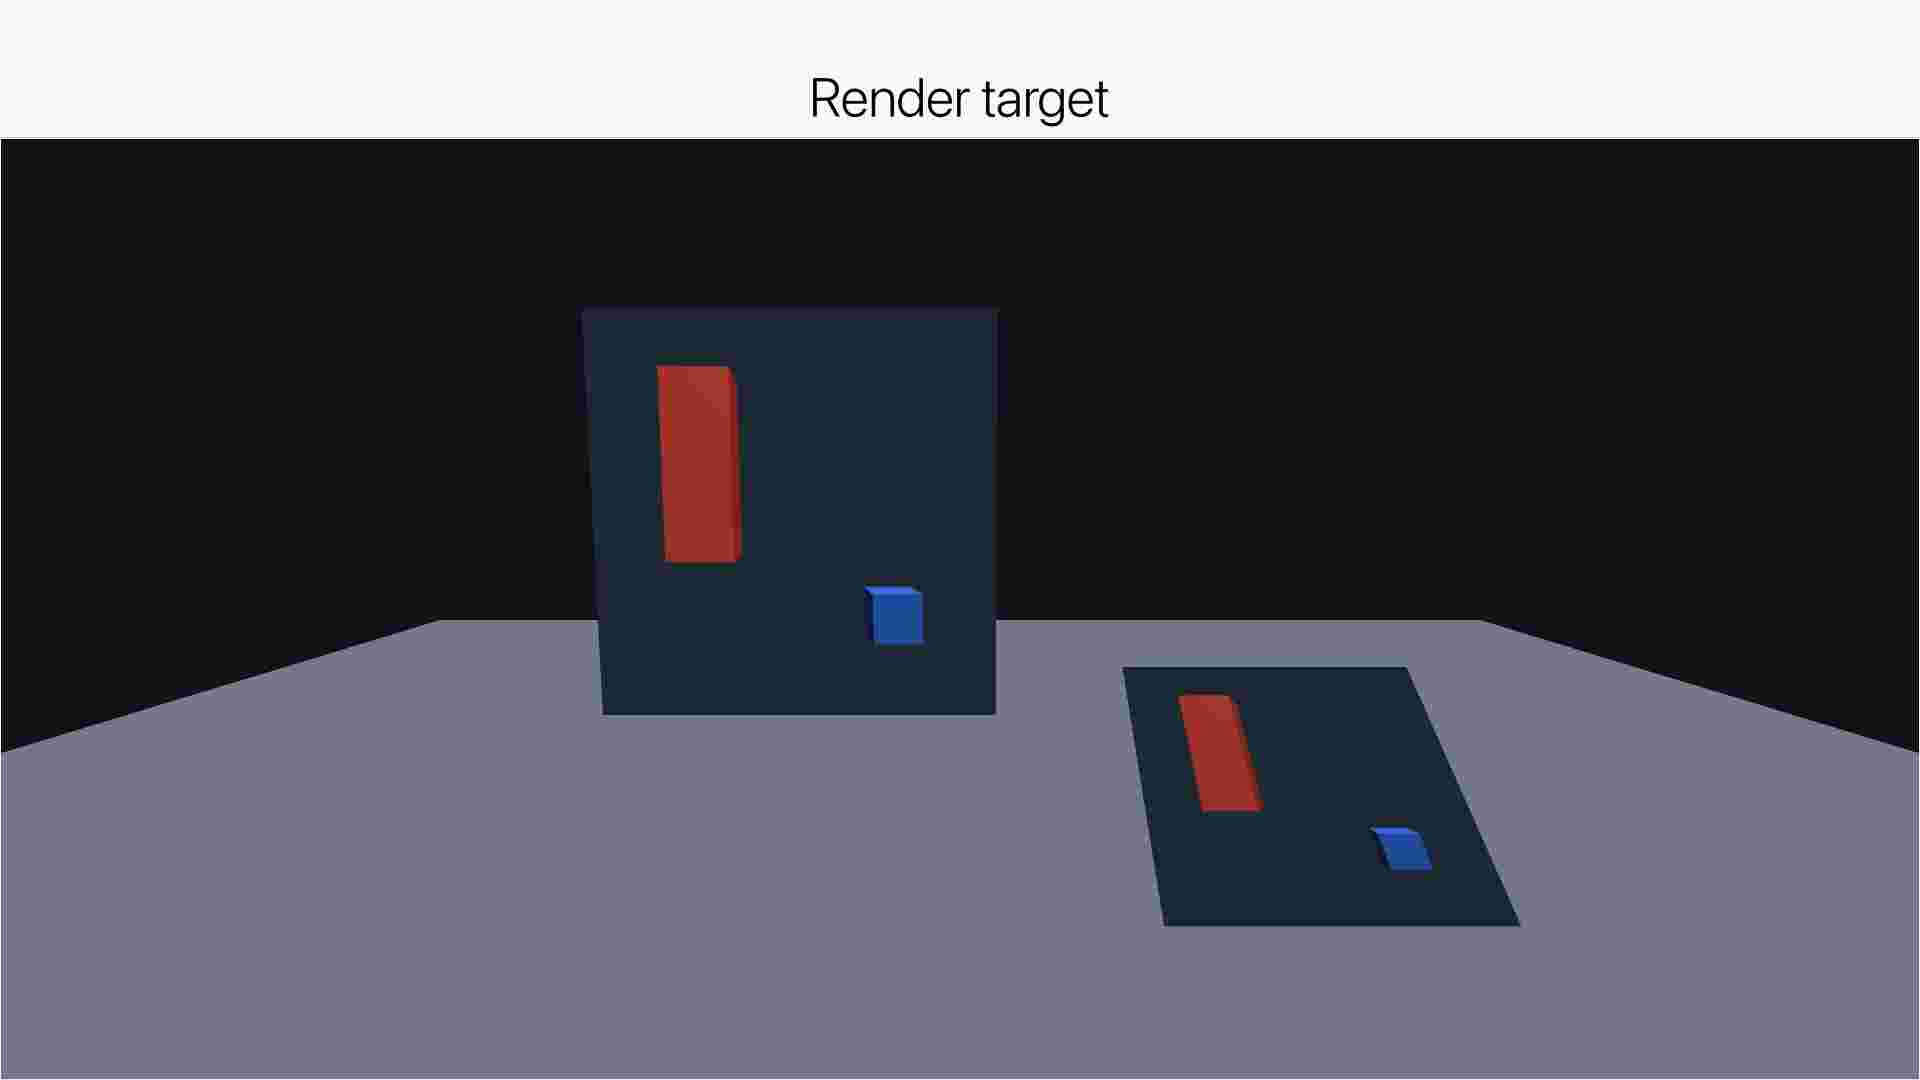
    • render targets
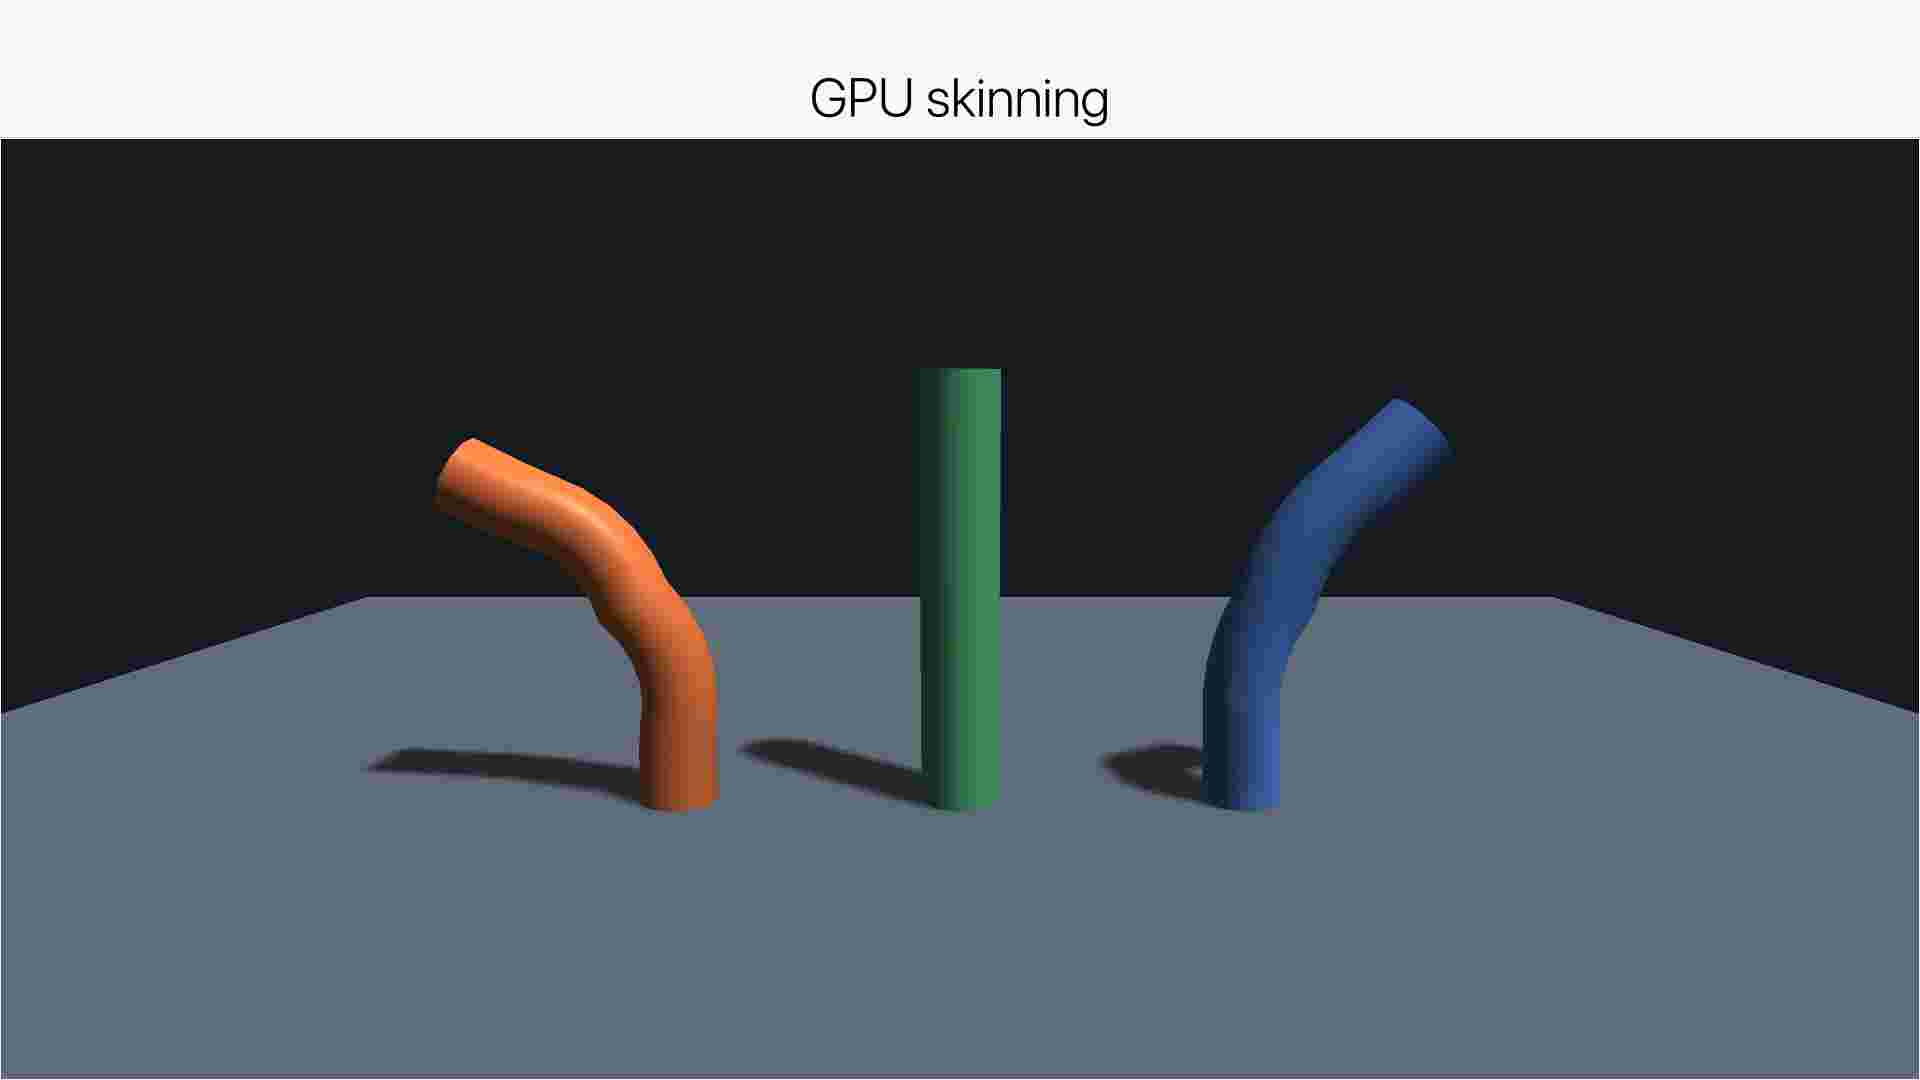
    • GPU skinning
    • instancing
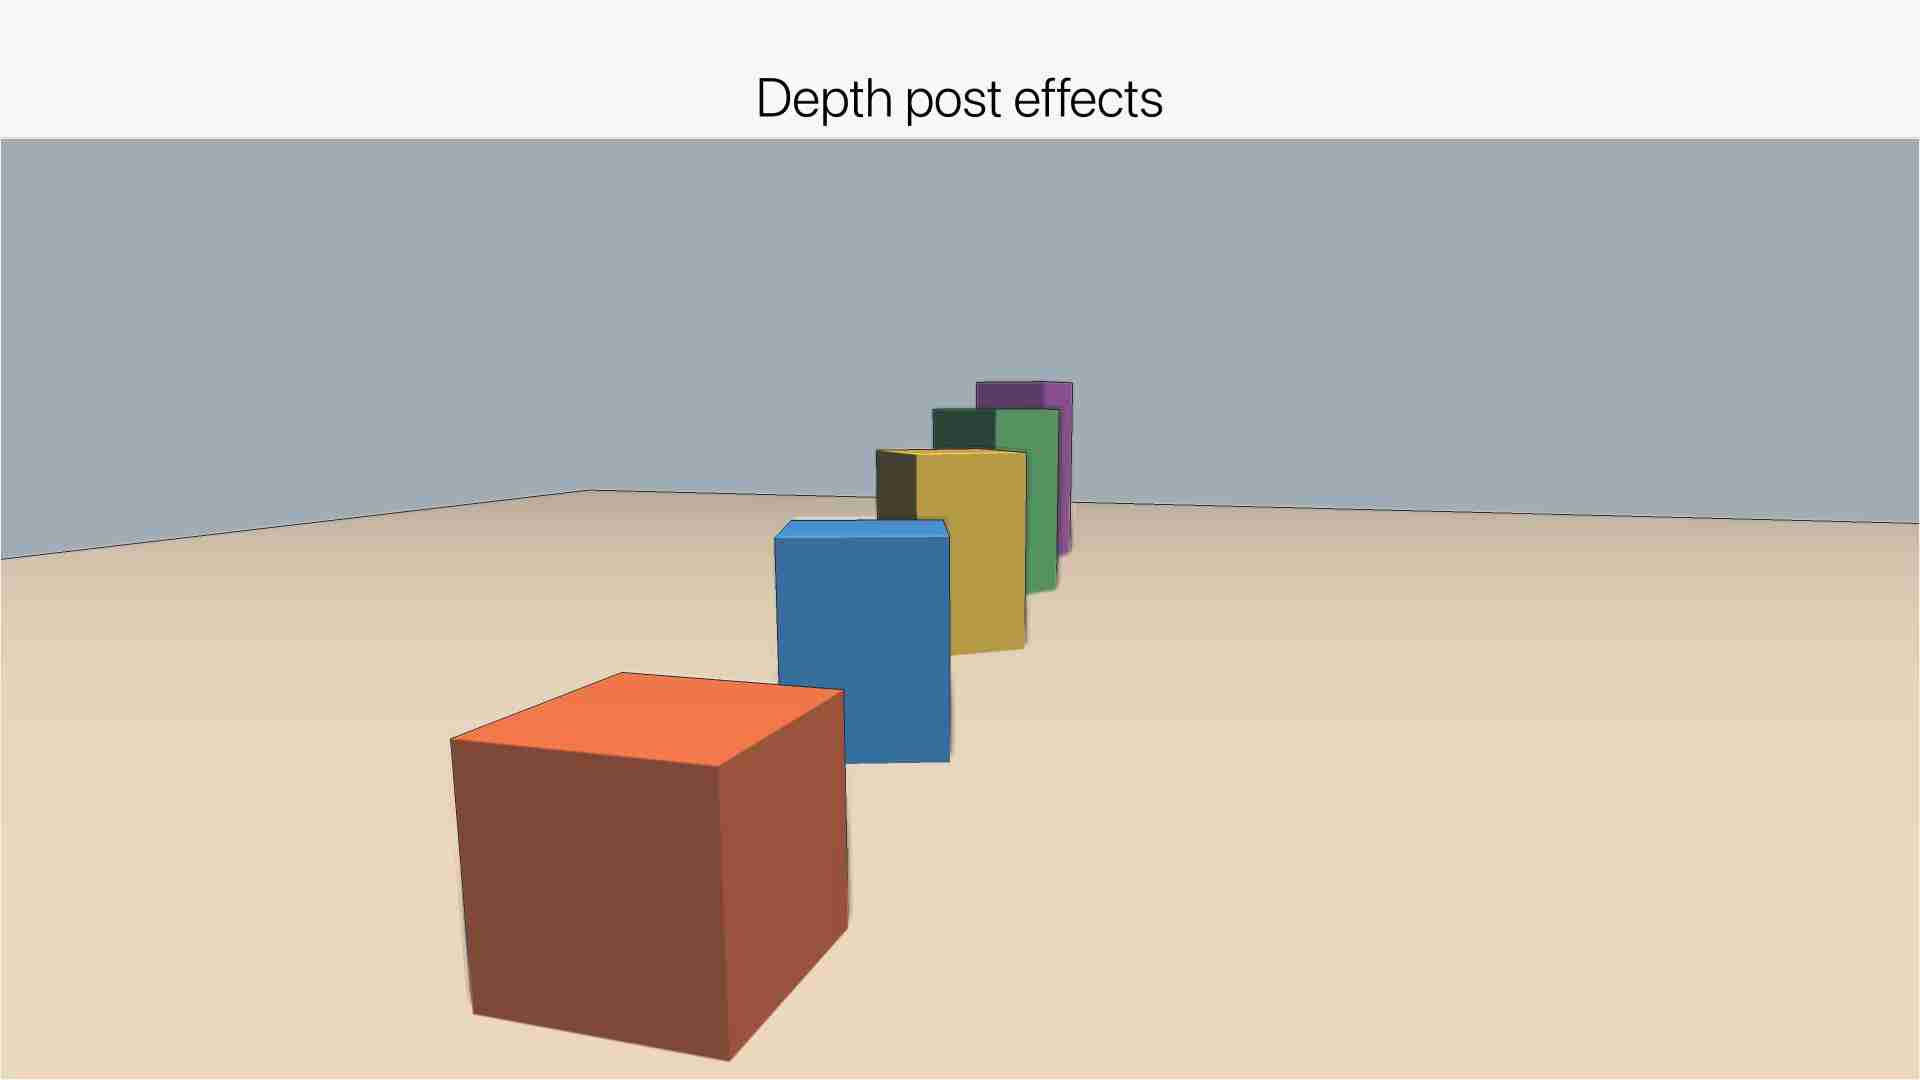
    • post effects: AO, depth of field, god rays, outline and FXAA
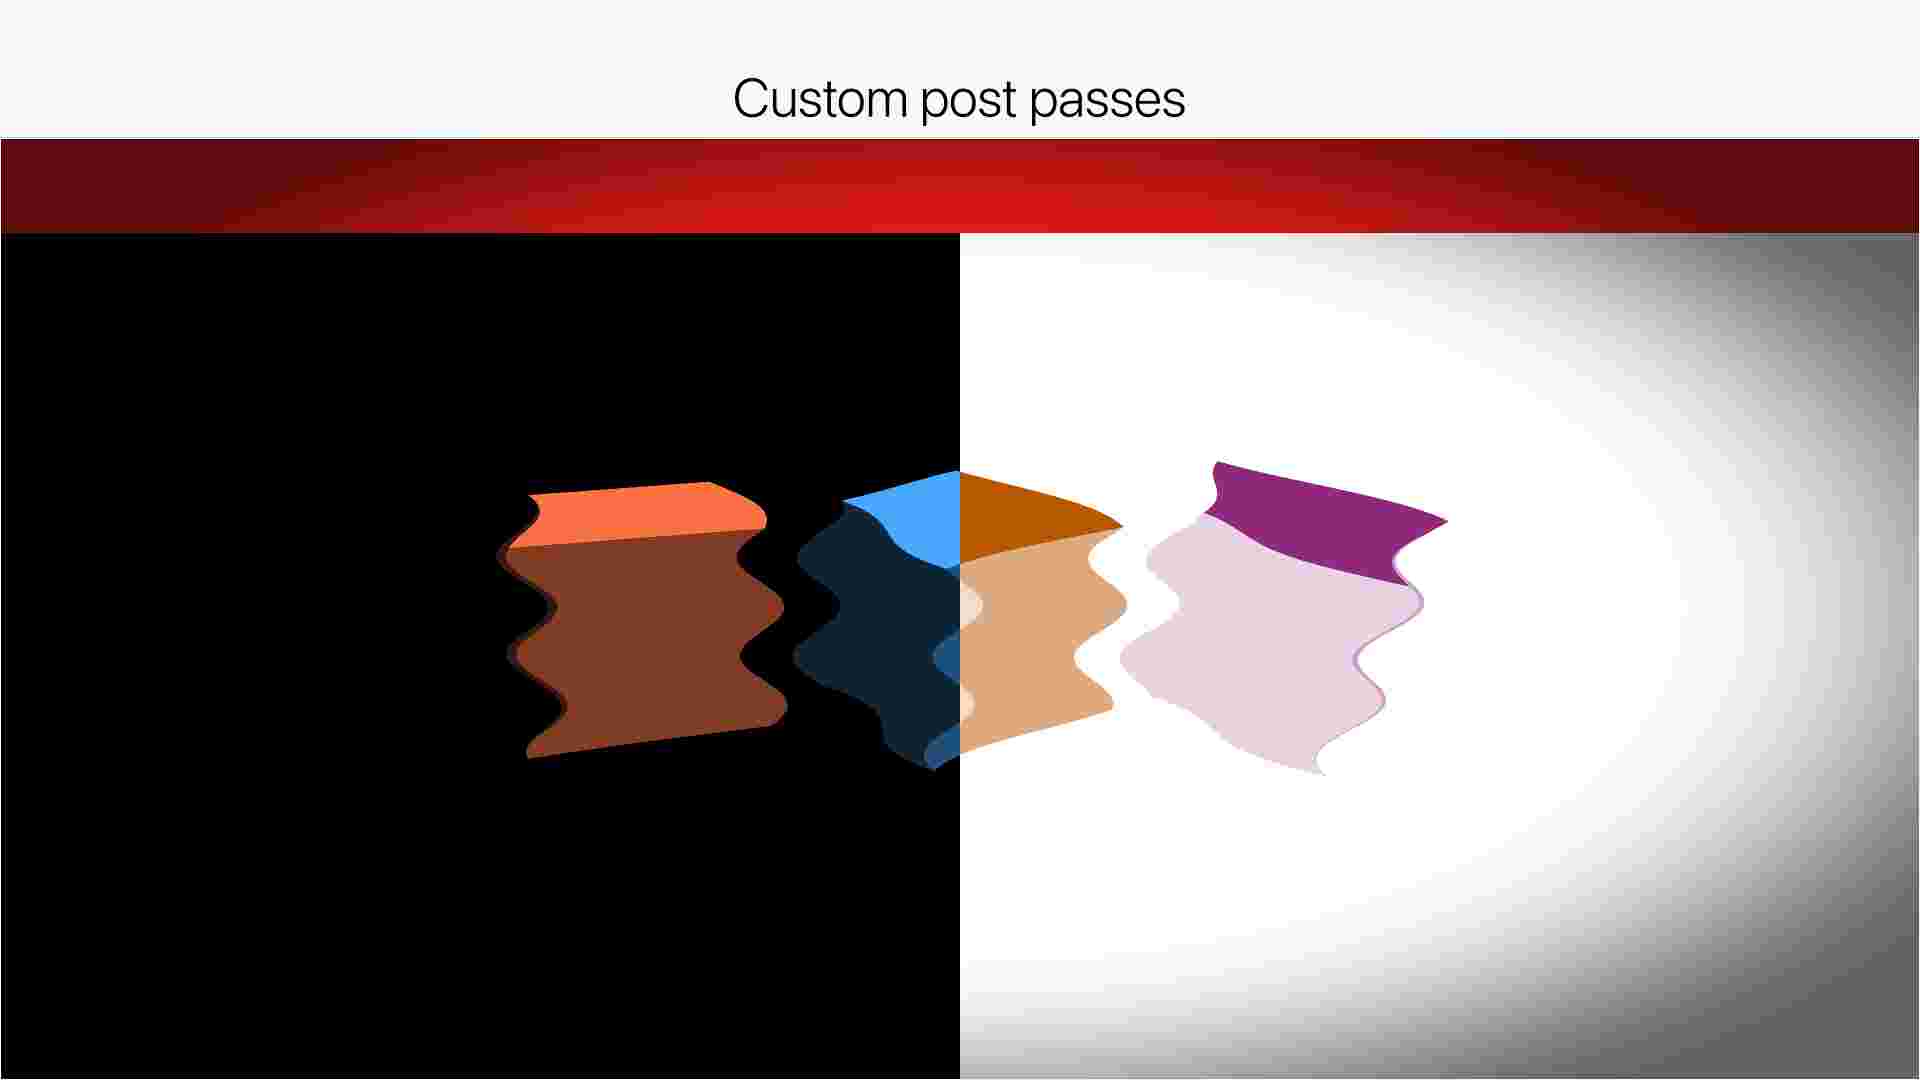
    • custom full-screen passes (PostProcess.addPass)
  • Splat uses the library. Its screenshots and release videos are recaptured.
  • AnimatedModel.getBounds(): measures a posed model correctly when the device skins on the GPU.

Verification

  • Shader compiles: scripts/check-gpu-shaders.sh runs the real compilers (glslang, xcrun metal, HLSL) over every emitted program. 268 compiles, clean.
  • Screenshot tests: a Gpu* hellocodenameone test per feature, including GpuSkinning and GpuPostPass. Their new goldens are seeded from CI.
  • Unit tests: core-unittests pass, with PMD and SpotBugs at zero. One timing test, ScrollWheelGestureTest, failed once in the full run and passes alone.
  • Native gates: native signatures, C++ linkage and control characters are clean.

Commits

  • gpu: AnimatedModel.getBounds, scalar lowering, logged pass drops; recapture Splat shots
  • website: re-record the Splat release demos with the new GPU features
  • gpu: custom full screen passes in the post chain on every backend
  • gpu: skinning in the vertex stage on every backend
  • gpu: close the macOS shadow-pass stub so the render-target stubs are not nested
  • gpu: depth post effects and colour lookup on every backend
  • gpu: render targets on every backend
  • gpu: image based lighting on every backend
  • gpu: two shadow cascades on every backend
  • website: re-record the Splat videos and posters
  • gpu: shadow casters run their custom shader's vertex offset and discard
  • docs: re-capture the Splat screenshots with the shader library materials
  • docs: custom shaders, the shader library, presets and instancing in the 3D chapter
  • hellocodenameone: shader library screenshot tests (harbour scene, gallery)
  • gpu: god rays, chromatic aberration and FXAA; instancing; a running shader clock; Splat on the library
  • gpu: shader library (com.codename1.gpu.shaders), scene presets, Primitives.grid, Material.setFogged
  • gpu: normal, detail, occlusion, emissive and metal-rough maps; analytic sky IBL; soft shadows
  • gpu: portable shader graphs (ShaderNode/ShaderMaterial) on every backend

🤖 Generated with Claude Code

shai-almog and others added 19 commits November 13, 2026 17:12
A typed Java expression graph, printed to GLSL ES, MSL and HLSL by one
emitter, replaces inputs of the engine's own shader through hooks (vertex
offset, base colour, normal, metallic, roughness, emissive, discard), so a
custom surface keeps lighting, shadows, fog and tone mapping. Per-material
uniforms (16 vec4 slots) and textures (units 2-5) plus a clock are bound by
the GL, Metal, D3D11 and Linux GLES backends; ShaderEvaluator runs the same
graphs on the CPU for the software rasterizer and for gameplay code.

Co-Authored-By: Claude Opus 5.5 <noreply@anthropic.com>
…ic sky IBL; soft shadows

Material maps compose into the material's ShaderMaterial (getEffectiveShader),
so every backend gets them through the existing hooks with no new vertex
layout: the tangent frame is derived from the surface normal
(ShaderNode.perturbNormal). glTF normal/occlusion/emissive/metallicRoughness
textures load onto AnimatedModel parts. PBR ambient now reflects the
hemisphere along the roughness-blurred reflection ray with Karis' fitted
split-sum BRDF on GLSL, Metal and HLSL. Light.setShadowSoftness widens the
3x3 PCF kernel on all six devices.

Co-Authored-By: Claude Opus 5.5 <noreply@anthropic.com>
…tives.grid, Material.setFogged

Water, terrain, foliage, surfaces, toon, FX, liquids and sky built only
from public ShaderNode calls, plus six lighting presets. Every factory is
emitted through GLSL and evaluated on the CPU in ShaderLibraryTest, and
compiled with the Metal compiler locally.

Co-Authored-By: Claude Opus 5.5 <noreply@anthropic.com>
…hader clock; Splat on the library

PostProcess gains setGodRays, setChromaticAberration and setFxaa, written
once (GlslShaderGenerator.postEffects) and printed into the GLSL, Metal and
HLSL composites, with the parameters packed by GraphicsDevice.packPostEffects
on all seven devices and the iOS, Windows and Linux natives.

GraphicsDevice.drawInstanced and Model.setInstances draw copies of a mesh
that shaders tell apart with ShaderNode.instanceId, instanceRandom and
instanceColor. SpriteRenderer now advances the clock ShaderNode.time reads.

scripts/check-gpu-shaders.sh compiles every library shader and the
composite with glslang (GLSL ES 100, and HLSL through SPIR-V) and Metal;
PR CI runs it.

Splat: soft shadows, wind in its trees and bushes, puddles and grit on the
ground, thick glossy paint, FXAA, god rays and a touch of lens fringe.

Co-Authored-By: Claude Opus 5.5 <noreply@anthropic.com>
…lery)

Co-Authored-By: Claude Opus 5.5 <noreply@anthropic.com>
…he 3D chapter

Co-Authored-By: Claude Opus 5.5 <noreply@anthropic.com>
A material whose ShaderMaterial moves vertices or discards fragments now casts
the shadow of what is drawn: every backend builds a depth-only variant of the
material's own program (GLSL packed depth, Metal depth-only pipeline with a
discard-only fragment, HLSL R32 depth) for the shadow pass.

Co-Authored-By: Claude Opus 5.5 <noreply@anthropic.com>
Light.setShadowCascades(2, farExtent) splits the shadow map into a near and a
far square of one atlas. The far cascade is the near view scaled in x and y,
so receivers need only the ratio (the fourth shadow parameter) and pick the
near square when the point falls inside it. Casters draw once per cascade
into their own viewport. gl3dBeginShadowPass takes the atlas width on iOS,
Mac, watch, Windows and Linux; inside a Metal shadow pass gl3dSetViewport
moves the shadow encoder's viewport instead of recording the frame's.

Co-Authored-By: Claude Opus 5.5 <noreply@anthropic.com>
EnvironmentMaps bakes a sky or an equirect panorama into a six band
roughness atlas (plain 2D RGBA8, clamp, so GLES2/WebGL1 sample it);
Environment.setEnvironmentMap switches the lit generators to sample it
for ambient and the PBR specular. Bound on unit/slot 6 by the GL, Linux,
Metal and D3D devices. Fixes the polar-row blur radius overrunning its
weight table.

Co-Authored-By: Claude Opus 5.5 <noreply@anthropic.com>
GraphicsDevice.createRenderTarget/beginRenderTarget/endRenderTarget draw
into an ordinary Texture that later draws sample. GL devices flip clip
space Y and the winding inside a target so its texture comes out upright
like Metal's and Direct3D's. New natives gl3dCreateRenderTarget,
gl3dBeginRenderTarget and gl3dEndRenderTarget on iOS (Metal pass of its
own), Linux (shared FBO + depth) and Windows (RTV + DSV per target), with
Mac, watch and embedded stubs. GpuRenderTargetScreenshotTest shows it.

Co-Authored-By: Claude Opus 5.5 <noreply@anthropic.com>
Ambient occlusion, depth of field and outlines read the scene's depth in
the composite pass; a colour lookup strip (ColorLuts) maps the graded
colour. The shader text is shared by GLSL, Metal and HLSL. The GL
devices render the scene into a depth texture (falling back, with the
depth effects off, where ES 2 / WebGL 1 lack one), Metal stores and
samples its depth attachment, Direct3D views a typeless depth buffer.
Windows now uploads the whole post constant block; it copied 24 floats
and dropped the FXAA, aberration and god ray parameters.

Co-Authored-By: Claude Opus 5.5 <noreply@anthropic.com>
…not nested

Co-Authored-By: Claude Opus 5.5 <noreply@anthropic.com>
…apture Splat shots

Splat and Skirmish measured operators from part buffers at a stride of
eight floats, which on a GPU-skinned device hold the sixteen-float bind
pose, so the framing collapsed and the characters fell out of view.
AnimatedModel.getBounds measures the posed model on either path.

Co-Authored-By: Claude Opus 5.5 <noreply@anthropic.com>
…tubs

Co-Authored-By: Claude Opus 5.5 <noreply@anthropic.com>
@github-actions

Copy link
Copy Markdown
Contributor

Cloudflare Preview

@github-actions

github-actions Bot commented Nov 13, 2026 •

Copy link
Copy Markdown
Contributor

Developer Guide build artifacts are available for download from this workflow run:

Developer Guide quality checks:

  • AsciiDoc linter: No issues found (report)
  • Vale: No alerts found (report)
  • Paragraph capitalization: No paragraph capitalization issues (report)
  • LanguageTool: No grammar matches (report)
  • Image references: No unused images detected (report)

@github-actions

github-actions Bot commented Nov 13, 2026 •

Copy link
Copy Markdown
Contributor

✅ Continuous Quality Report

Test & Coverage

Static Analysis

  • SpotBugs [Report archive]
    • ✅ ByteCodeTranslator: 0 findings (no issues)
    • ✅ android: 0 findings (no issues)
    • ✅ android-compat: 0 findings (no issues)
    • ✅ android-res-compiler: 0 findings (no issues)
    • ✅ backend: 0 findings (no issues)
    • ✅ backend-test: 0 findings (no issues)
    • ✅ build-engine: 0 findings (no issues)
    • ✅ build-hint-catalog: 0 findings (no issues)
    • ✅ build-hint-tools: 0 findings (no issues)
    • ✅ codenameone-gradle-plugin: 0 findings (no issues)
    • ✅ codenameone-maven-plugin: 0 findings (no issues)
    • ✅ compose-compat: 0 findings (no issues)
    • ✅ core-unittests: 0 findings (no issues)
    • ✅ desktop-compat-runtime: 0 findings (no issues)
    • ✅ fxml-compiler: 0 findings (no issues)
    • ✅ ios: 0 findings (no issues)
    • ✅ javac: 0 findings (no issues)
    • ✅ javafx-compat: 0 findings (no issues)
    • ✅ project-model: 0 findings (no issues)
    • ✅ python-runtime: 0 findings (no issues)
    • ✅ python-transpiler: 0 findings (no issues)
    • ✅ swing-compat: 0 findings (no issues)
  • ✅ PMD: 0 findings (no issues) [Report archive]
  • ✅ Checkstyle: 0 findings (no issues) [Report archive]

Generated automatically by the PR CI workflow.

@github-actions

github-actions Bot commented Nov 13, 2026 •

Copy link
Copy Markdown
Contributor

✅ ByteCodeTranslator Quality Report

Test & Coverage

  • ✅ Tests: 934 total, 0 failed, 55 skipped

Benchmark Results

  • Execution Time: 7582 ms

  • Hotspots (Top 20 sampled methods):

    • 9.34% java.util.ArrayList.indexOf (95 samples)
    • 8.65% java.lang.System.identityHashCode (88 samples)
    • 5.70% java.lang.Object.hashCode (58 samples)
    • 5.01% com.codename1.tools.translator.classfile.analysis.Frame.execute (51 samples)
    • 4.42% java.lang.StringBuilder.append (45 samples)
    • 3.64% com.codename1.tools.translator.BytecodeMethod.equals (37 samples)
    • 2.56% com.codename1.tools.translator.bytecodes.Invoke.findMethodUp (26 samples)
    • 2.26% java.lang.String.equals (23 samples)
    • 1.87% java.util.HashMap.hash (19 samples)
    • 1.67% com.codename1.tools.translator.BytecodeMethod.updateInlinableFieldDependencies (17 samples)
    • 1.57% com.codename1.tools.translator.bytecodes.Invoke.resolveDirectTarget (16 samples)
    • 1.47% com.codename1.tools.translator.ByteCodeClass.markDependencies (15 samples)
    • 1.47% com.codename1.tools.translator.ByteCodeClass.hasDeclaredMethod (15 samples)
    • 1.38% com.codename1.tools.translator.Parser.cullMethods (14 samples)
    • 0.98% com.codename1.tools.translator.DeadFieldElimination.run (10 samples)
    • 0.98% java.io.FileOutputStream.writeBytes (10 samples)
    • 0.98% com.codename1.tools.translator.ByteCodeClass.hasDeclaredNonAbstractMethod (10 samples)
    • 0.98% com.codename1.tools.translator.Parser.generateClassAndMethodIndexHeader (10 samples)
    • 0.88% java.util.TreeMap.getEntry (9 samples)
    • 0.88% com.codename1.tools.translator.BytecodeMethod.addToConstantPool (9 samples)
  • ⚠️ Coverage report not generated.

Static Analysis

  • ✅ SpotBugs: no findings (report was not generated by the build).
  • ⚠️ PMD report not generated.
  • ⚠️ Checkstyle report not generated.

Generated automatically by the PR CI workflow.

@shai-almog

shai-almog commented Nov 14, 2026 •

Copy link
Copy Markdown
Collaborator Author

Compared 210 screenshots: 210 matched.
✅ Native Mac screenshot tests passed.

Benchmark Results

  • VM Translation Time: 0 seconds
  • Compilation Time: 579 seconds

Detailed Performance Metrics

Metric Duration
SIMD kernel backend SSE2 (x64) / NEON (arm64) native kernels
SIMD int-add (64K x300) java 52ms / native 2ms = 26.0x speedup
SIMD float-mul (64K x300) java 51ms / native 3ms = 17.0x speedup
SIMD kernel correctness PASS (native result == scalar reference)
Base64 native bridge unavailable (CN1 + SIMD + image benchmarks only)
Base64 payload size 8192 bytes
Base64 benchmark iterations 6000
Base64 SIMD byte path active (NEON-accelerated)
Base64 CN1 encode 43.000 ms
Base64 CN1 decode 54.000 ms
Image encode benchmark iterations 100
Image createMask (SIMD off) 7.000 ms
Image createMask (SIMD on) 4.000 ms
Image createMask ratio (SIMD on/off) 0.571x (42.9% faster)
Image applyMask (SIMD off) 55.000 ms
Image applyMask (SIMD on) 63.000 ms
Image applyMask ratio (SIMD on/off) 1.145x (14.5% slower)
Image modifyAlpha (SIMD off) 54.000 ms
Image modifyAlpha (SIMD on) 45.000 ms
Image modifyAlpha ratio (SIMD on/off) 0.833x (16.7% faster)
Image modifyAlpha removeColor (SIMD off) 51.000 ms
Image modifyAlpha removeColor (SIMD on) 45.000 ms
Image modifyAlpha removeColor ratio (SIMD on/off) 0.882x (11.8% faster)

ParparVM vs HotSpot (JDK 25): macOS arm64

Runner CPU: Apple M1 (Virtual) (baseline macos-arm64)

Ratios are ParparVM / JDK 25: below 1.00x ParparVM is faster (time) or smaller (RAM). Median of 5 interleaved, paired rounds; every run's output was verified. A ratio more than 20% (time) / 25% (RAM) above its baseline in vm/selfhost/perf-baseline/ is a regression and fails; one that far below is an improvement, reported but not failed (a row whose calibration runs were noisier carries a wider tolerance), and for RAM the change must also exceed 0.05x in absolute terms. Both run unpinned on all of the runner's CPUs, with their own default thread counts.

Benchmark Cores Time RAM Status
hello (HelloCodenameOne) 3 1.10x (base 0.96x, +14.7%) 0.88x (base 0.93x, -4.7%) ok
translator (self) 3 0.65x (base 0.62x, +3.9%) 0.78x (base 0.78x, -0.2%) ok
intArithmetic 3 1.04x (base 1.03x, +0.6%) 0.12x (base 0.12x, +1.5%) ok
longArithmetic 3 1.00x (base 1.03x, -2.4%) 0.11x (base 0.07x, +60.2%) ok
mathTranscendental 3 0.96x (base 1.01x, -4.3%) 0.12x (base 0.12x, +0.6%) ok
arraySequential 3 0.45x (base 0.42x, +7.4%) 0.53x (base 0.53x, +0.4%) ok
arrayRandom 3 0.98x (base 0.99x, -1.0%) 0.32x (base 0.32x, +0.2%) ok
objectAllocation 3 1.04x (base 1.11x, -5.6%) 0.74x (base 0.72x, +2.6%) ok
valueEscape 3 0.51x (base 0.51x, +0.4%) 0.09x (base 0.09x, -0.2%) ok
hashMapChurn 3 1.08x (base 1.18x, -7.8%) 0.07x (base 0.07x, +4.9%) ok
stringBuilding 3 0.94x (base 0.84x, +11.4%) 0.46x (base 0.46x, +0.4%) ok
recursion 3 1.27x (base 1.24x, +2.8%) 0.12x (base 0.12x, +0.2%) ok
quicksort 3 1.00x (base 1.01x, -1.6%) 0.11x (base 0.11x, +1.0%) ok

Result: no regression

@shai-almog

shai-almog commented Nov 14, 2026 •

Copy link
Copy Markdown
Collaborator Author

Compared 230 screenshots: 230 matched.
Native Windows port (x64 / Intel-AMD): full hellocodenameone screenshot suite rendered offscreen with Direct2D/DirectWrite, plus the real benchmarks (base64 native/CN1/SIMD, image createMask/applyMask/modifyAlpha/PNG/JPEG, SSE2 SIMD kernels). Compared against the in-repo baseline in scripts/windows/screenshots.

Benchmark Results

Detailed Performance Metrics

Metric Duration
SIMD kernel backend SSE2 (x64) / NEON (arm64) native kernels
SIMD int-add (64K x300) java 56ms / native 4ms = 14.0x speedup
SIMD float-mul (64K x300) java 56ms / native 3ms = 18.6x speedup
SIMD kernel correctness PASS (native result == scalar reference)
Base64 native bridge unavailable (CN1 + SIMD + image benchmarks only)
Base64 payload size 8192 bytes
Base64 benchmark iterations 6000
Base64 SIMD byte path gated to scalar (CPU autovectorizes scalar; explicit SIMD not beneficial here)
Base64 CN1 encode 85.000 ms
Base64 CN1 decode 99.000 ms
Base64 SIMD encode 119.000 ms
Base64 encode ratio (SIMD/CN1) 1.400x (40.0% slower)
Base64 SIMD decode 98.000 ms
Base64 decode ratio (SIMD/CN1) 0.990x (1.0% faster)
Image encode benchmark iterations 100
Image createMask (SIMD off) 11.000 ms
Image createMask (SIMD on) 5.000 ms
Image createMask ratio (SIMD on/off) 0.455x (54.5% faster)
Image applyMask (SIMD off) 20.000 ms
Image applyMask (SIMD on) 21.000 ms
Image applyMask ratio (SIMD on/off) 1.050x (5.0% slower)
Image modifyAlpha (SIMD off) 39.000 ms
Image modifyAlpha (SIMD on) 26.000 ms
Image modifyAlpha ratio (SIMD on/off) 0.667x (33.3% faster)
Image modifyAlpha removeColor (SIMD off) 43.000 ms
Image modifyAlpha removeColor (SIMD on) 19.000 ms
Image modifyAlpha removeColor ratio (SIMD on/off) 0.442x (55.8% faster)

ParparVM vs HotSpot (JDK 25): Windows x64

Runner CPU: AMD64 Family 25 Model 1 Stepping 1, AuthenticAMD (baseline windows-x64@amd64-family-25-model-1-authenticamd)

Ratios are ParparVM / JDK 25: below 1.00x ParparVM is faster (time) or smaller (RAM). Median of 5 interleaved, paired rounds; every run's output was verified. A ratio more than 20% (time) / 25% (RAM) above its baseline in vm/selfhost/perf-baseline/ is a regression and fails; one that far below is an improvement, reported but not failed (a row whose calibration runs were noisier carries a wider tolerance), and for RAM the change must also exceed 0.05x in absolute terms. Both run unpinned on all of the runner's CPUs, with their own default thread counts.

Benchmark Cores Time RAM Status
hello (WinHelloMain) 4 1.73x (base 1.22x, +41.7%) 0.76x (base 0.58x, +30.5%) ok
translator (self) 4 0.77x (base 0.83x, -7.6%) 0.60x (base 0.54x, +9.9%) ok
intArithmetic 4 1.10x (base 1.10x, -0.0%) 0.06x (base 0.06x, +3.0%) ok
longArithmetic 4 1.14x (base 1.08x, +5.1%) 0.06x (base 0.05x, +3.5%) ok
mathTranscendental 4 0.79x (base 0.79x, -0.5%) 0.06x (base 0.06x, +3.2%) ok
arraySequential 4 1.33x (base 1.36x, -2.5%) 0.39x (base 0.39x, +0.3%) ok
arrayRandom 4 0.84x (base 1.06x, -21.1%) 0.23x (base 0.23x, +0.6%) ok
objectAllocation 4 1.57x (base 1.56x, +0.5%) 0.30x (base 0.39x, -22.5%) ok
valueEscape 4 0.10x (base 0.10x, +0.3%) 0.05x (base 0.04x, +2.8%) ok
hashMapChurn 4 1.81x (base 1.80x, +0.7%) 0.09x (base 0.09x, -0.8%) ok
stringBuilding 4 1.21x (base 1.22x, -0.7%) 0.27x (base 0.32x, -17.1%) ok
recursion 4 1.41x (base 1.49x, -5.8%) 0.06x (base 0.06x, +1.8%) ok
quicksort 4 1.12x (base 1.13x, -1.5%) 0.12x (base 0.12x, +0.9%) ok

Result: no regression

…ples; snapshot queued JS host-call arrays; complete LUT textures on Android/JavaSE GL; seed goldens

- JS runtime marshalled fire-and-forget host-call arrays at flush time, so a
  reused array gave every queued call its last value (all skinned meshes
  posed by the last joint palette). Arrays are copied when queued.
- Android and JavaSE GL uploads left the default mipmapped min filter on a
  texture with no mipmaps: incomplete, sampled black (the post colour LUT).
- Shader gallery test waits for drawn frames instead of a fixed timer.

Co-Authored-By: Claude Opus 5.5 <noreply@anthropic.com>
@shai-almog

shai-almog commented Nov 14, 2026 •

Copy link
Copy Markdown
Collaborator Author

Compared 12 screenshots: 12 matched.
✅ JavaSE simulator integration screenshots matched stored baselines.

shai-almog and others added 3 commits November 14, 2026 05:42
…ldens; keep Splat on released API

Harbour, RenderTarget, PostDepth and Skinning captured a blank view on the
Android emulator legs where the first frame's program compiles outlast the
fixed timer; they now poll until two frames have completed, as the gallery
does. Splat's e2e build compiles against the published release, which has
no shader API yet, so ArenaView goes back to master's materials.

Co-Authored-By: Claude Opus 5.5 <noreply@anthropic.com>
… hello on windows-x64

The guide validator allows nothing but the include inside a source block.
The hello suite's ParparVM/JVM time ratio on windows-x64 rose with the six
new Gpu tests (CPU-side IBL and noise baking), not with a VM change.

Co-Authored-By: Claude Opus 5.5 <noreply@anthropic.com>
shai-almog and others added 4 commits November 14, 2026 07:38
Both blocks are parts of a renderer (a material, a GraphicsDevice set-up)
and cannot compile as a standalone Playground script.

Co-Authored-By: Claude Opus 5.5 <noreply@anthropic.com>
…r Java 8

Master's pr.yml build-test (8) fails to compile AndroidCameraImpl at
startVideoRecording since #6231.

Co-Authored-By: Claude Opus 5.5 <noreply@anthropic.com>
@shai-almog

shai-almog commented Nov 14, 2026 •

Copy link
Copy Markdown
Collaborator Author

Compared 215 screenshots: 215 matched.

Native Android coverage

  • 📊 Line coverage: 19.35% (56889/293959 lines covered) [HTML preview] (artifact android-coverage-report, jacocoAndroidReport/html/index.html)
    • Other counters: instruction 18.35% (274840/1498108), branch 12.43% (19799/159285), complexity 10.44% (16016/153377), method 15.88% (11546/72707), class 28.19% (2278/8080)
    • Lowest covered classes
      • kotlin.collections.unsigned.kotlin.collections.unsigned.UArraysKt___UArraysKt – 0.00% (0/2396 lines covered)
      • org.jacoco.agent.rt.internal_0e20598.asm.org.jacoco.agent.rt.internal_0e20598.asm.ClassReader – 0.00% (0/1524 lines covered)
      • androidx.compose.runtime.androidx.compose.runtime.LinkComposer – 0.00% (0/1430 lines covered)
      • org.jacoco.agent.rt.internal_0e20598.asm.org.jacoco.agent.rt.internal_0e20598.asm.MethodWriter – 0.00% (0/922 lines covered)
      • kotlinx.coroutines.channels.kotlinx.coroutines.channels.BufferedChannel – 0.00% (0/863 lines covered)
      • kotlin.sequences.kotlin.sequences.SequencesKt___SequencesKt – 0.00% (0/744 lines covered)
      • com.google.common.cache.com.google.common.cache.LocalCache$Segment – 0.00% (0/726 lines covered)
      • okio.okio.Buffer – 0.00% (0/687 lines covered)
      • kotlin.text.kotlin.text.StringsKt___StringsKt – 0.00% (0/630 lines covered)
      • com.codename1.androidcompat.rt.com.codename1.androidcompat.rt.TextXmlPullParser – 0.00% (0/623 lines covered)

✅ Native Android screenshot tests passed.

Native Android coverage

  • 📊 Line coverage: 19.35% (56889/293959 lines covered) [HTML preview] (artifact android-coverage-report, jacocoAndroidReport/html/index.html)
    • Other counters: instruction 18.35% (274840/1498108), branch 12.43% (19799/159285), complexity 10.44% (16016/153377), method 15.88% (11546/72707), class 28.19% (2278/8080)
    • Lowest covered classes
      • kotlin.collections.unsigned.kotlin.collections.unsigned.UArraysKt___UArraysKt – 0.00% (0/2396 lines covered)
      • org.jacoco.agent.rt.internal_0e20598.asm.org.jacoco.agent.rt.internal_0e20598.asm.ClassReader – 0.00% (0/1524 lines covered)
      • androidx.compose.runtime.androidx.compose.runtime.LinkComposer – 0.00% (0/1430 lines covered)
      • org.jacoco.agent.rt.internal_0e20598.asm.org.jacoco.agent.rt.internal_0e20598.asm.MethodWriter – 0.00% (0/922 lines covered)
      • kotlinx.coroutines.channels.kotlinx.coroutines.channels.BufferedChannel – 0.00% (0/863 lines covered)
      • kotlin.sequences.kotlin.sequences.SequencesKt___SequencesKt – 0.00% (0/744 lines covered)
      • com.google.common.cache.com.google.common.cache.LocalCache$Segment – 0.00% (0/726 lines covered)
      • okio.okio.Buffer – 0.00% (0/687 lines covered)
      • kotlin.text.kotlin.text.StringsKt___StringsKt – 0.00% (0/630 lines covered)
      • com.codename1.androidcompat.rt.com.codename1.androidcompat.rt.TextXmlPullParser – 0.00% (0/623 lines covered)

Benchmark Results

Detailed Performance Metrics

Metric Duration
SIMD kernel backend scalar fallback (no native SIMD)
SIMD int-add (64K x300) java 163ms / native 47ms = 3.4x speedup
SIMD float-mul (64K x300) java 101ms / native 92ms = 1.0x speedup
SIMD kernel correctness PASS (native result == scalar reference)
Base64 payload size 8192 bytes
Base64 benchmark iterations 6000
Base64 SIMD byte path gated to scalar (CPU autovectorizes scalar; explicit SIMD not beneficial here)
Base64 CN1 encode 47.000 ms
Base64 CN1 decode 60.000 ms
Base64 native encode 365.000 ms
Base64 encode ratio (CN1/native) 0.129x (87.1% faster)
Base64 native decode 244.000 ms
Base64 decode ratio (CN1/native) 0.246x (75.4% faster)
Image encode benchmark status skipped (SIMD unsupported)

@shai-almog

shai-almog commented Nov 14, 2026 •

Copy link
Copy Markdown
Collaborator Author

Compared 230 screenshots: 230 matched.
Native Windows port, REAL shipping pipeline: the hellocodenameone screenshot suite rendered by a binary CROSS-COMPILED on Linux (clang-cl + xwin, WebView2 linked) and RUN on a Windows x64 runner. Compared against the in-repo baseline in scripts/windows/screenshots.

Benchmark Results

Detailed Performance Metrics

Metric Duration
SIMD kernel backend SSE2 (x64) / NEON (arm64) native kernels
SIMD int-add (64K x300) java 44ms / native 3ms = 14.6x speedup
SIMD float-mul (64K x300) java 41ms / native 3ms = 13.6x speedup
SIMD kernel correctness PASS (native result == scalar reference)
Base64 native bridge unavailable (CN1 + SIMD + image benchmarks only)
Base64 payload size 8192 bytes
Base64 benchmark iterations 6000
Base64 SIMD byte path gated to scalar (CPU autovectorizes scalar; explicit SIMD not beneficial here)
Base64 CN1 encode 64.000 ms
Base64 CN1 decode 75.000 ms
Base64 SIMD encode 86.000 ms
Base64 encode ratio (SIMD/CN1) 1.344x (34.4% slower)
Base64 SIMD decode 77.000 ms
Base64 decode ratio (SIMD/CN1) 1.027x (2.7% slower)
Image encode benchmark iterations 100
Image createMask (SIMD off) 10.000 ms
Image createMask (SIMD on) 12.000 ms
Image createMask ratio (SIMD on/off) 1.200x (20.0% slower)
Image applyMask (SIMD off) 17.000 ms
Image applyMask (SIMD on) 18.000 ms
Image applyMask ratio (SIMD on/off) 1.059x (5.9% slower)
Image modifyAlpha (SIMD off) 24.000 ms
Image modifyAlpha (SIMD on) 19.000 ms
Image modifyAlpha ratio (SIMD on/off) 0.792x (20.8% faster)
Image modifyAlpha removeColor (SIMD off) 25.000 ms
Image modifyAlpha removeColor (SIMD on) 13.000 ms
Image modifyAlpha removeColor ratio (SIMD on/off) 0.520x (48.0% faster)

@shai-almog

shai-almog commented Nov 14, 2026 •

Copy link
Copy Markdown
Collaborator Author

Apple TV (tvOS / Metal)

Compared 207 screenshots: 202 matched, 5 missing references.

  • GpuPostDepth — missing reference. Reference screenshot missing at /Users/runner/work/CodenameOne/CodenameOne/scripts/ios/screenshots-tv/GpuPostDepth.png.

    GpuPostDepth
    Preview info: JPEG preview quality 20; JPEG preview quality 20; downscaled to 1920x1080.
    Full-resolution PNG saved as GpuPostDepth.png in workflow artifacts.

  • GpuPostPass — missing reference. Reference screenshot missing at /Users/runner/work/CodenameOne/CodenameOne/scripts/ios/screenshots-tv/GpuPostPass.png.

    GpuPostPass
    Preview info: JPEG preview quality 10; JPEG preview quality 10; downscaled to 1920x1080.
    Full-resolution PNG saved as GpuPostPass.png in workflow artifacts.

  • GpuRenderTarget — missing reference. Reference screenshot missing at /Users/runner/work/CodenameOne/CodenameOne/scripts/ios/screenshots-tv/GpuRenderTarget.png.

    GpuRenderTarget
    Preview info: JPEG preview quality 10; JPEG preview quality 10; downscaled to 1920x1080.
    Full-resolution PNG saved as GpuRenderTarget.png in workflow artifacts.

  • GpuShaderGallery — missing reference. Reference screenshot missing at /Users/runner/work/CodenameOne/CodenameOne/scripts/ios/screenshots-tv/GpuShaderGallery.png.

    GpuShaderGallery
    Preview info: JPEG preview quality 10; JPEG preview quality 10; downscaled to 1920x1080.
    Full-resolution PNG saved as GpuShaderGallery.png in workflow artifacts.

  • GpuSkinning — missing reference. Reference screenshot missing at /Users/runner/work/CodenameOne/CodenameOne/scripts/ios/screenshots-tv/GpuSkinning.png.

    GpuSkinning
    Preview info: JPEG preview quality 10; JPEG preview quality 10; downscaled to 1920x1080.
    Full-resolution PNG saved as GpuSkinning.png in workflow artifacts.

shai-almog and others added 5 commits November 14, 2026 19:33
…; Linux goldens; perf baseline

The Metal pipeline recovered the vertex stride from the first "|s" in its
key, which a custom shader ("|sh:") or skinned ("|skin3") material key now
contains ahead of the real "|sNN" segment. The stride parsed as zero, the
descriptor declared position alone and Metal rejected every pipeline that
reads a normal, uv or joints, so shader materials and skinned meshes were
missing on tvOS and iOS Metal. It now searches from the end for "|s" plus a
digit.

The GPU tests' frame gate could wait ~19.6s, past the 10s per-test budget
on HTML5, so a slow scene (GpuPostDepth) was killed before it captured; the
cap is 25 polls on HTML5 and 90 elsewhere.

Seeds the six new Gpu goldens for Linux x64 and arm64 and calibrates the
linux-x64 perf baseline for a runner CPU that had none.

Co-Authored-By: Claude Opus 5.5 <noreply@anthropic.com>
A depth-post frame on HTML5 outlasts the 200ms poll, so each poll queued
another render behind it; the backlog held the browser's main thread and
no timer fired until the test's 10s budget ran out (GpuPostDepth). The gate
now asks for a frame only once the previous request has started one.

Co-Authored-By: Claude Opus 5.5 <noreply@anthropic.com>
# Conflicts:
#	docs/developer-guide/languagetool-accept.txt
@shai-almog

shai-almog commented Nov 15, 2026 •

Copy link
Copy Markdown
Collaborator Author

Compared 230 screenshots: 230 matched.
Native Windows port (arm64 / Apple Silicon - Arm): full hellocodenameone screenshot suite rendered offscreen with Direct2D/DirectWrite, plus the real benchmarks (base64 native/CN1/SIMD, image createMask/applyMask/modifyAlpha/PNG/JPEG, NEON SIMD kernels). Compared against the in-repo baseline in scripts/windows/screenshots.

Benchmark Results

Detailed Performance Metrics

Metric Duration
SIMD kernel backend SSE2 (x64) / NEON (arm64) native kernels
SIMD int-add (64K x300) java 50ms / native 3ms = 16.6x speedup
SIMD float-mul (64K x300) java 52ms / native 2ms = 26.0x speedup
SIMD kernel correctness PASS (native result == scalar reference)
Base64 native bridge unavailable (CN1 + SIMD + image benchmarks only)
Base64 payload size 8192 bytes
Base64 benchmark iterations 6000
Base64 SIMD byte path gated to scalar (CPU autovectorizes scalar; explicit SIMD not beneficial here)
Base64 CN1 encode 62.000 ms
Base64 CN1 decode 67.000 ms
Base64 SIMD encode 76.000 ms
Base64 encode ratio (SIMD/CN1) 1.226x (22.6% slower)
Base64 SIMD decode 68.000 ms
Base64 decode ratio (SIMD/CN1) 1.015x (1.5% slower)
Image encode benchmark iterations 100
Image createMask (SIMD off) 6.000 ms
Image createMask (SIMD on) 2.000 ms
Image createMask ratio (SIMD on/off) 0.333x (66.7% faster)
Image applyMask (SIMD off) 14.000 ms
Image applyMask (SIMD on) 17.000 ms
Image applyMask ratio (SIMD on/off) 1.214x (21.4% slower)
Image modifyAlpha (SIMD off) 15.000 ms
Image modifyAlpha (SIMD on) 10.000 ms
Image modifyAlpha ratio (SIMD on/off) 0.667x (33.3% faster)
Image modifyAlpha removeColor (SIMD off) 21.000 ms
Image modifyAlpha removeColor (SIMD on) 10.000 ms
Image modifyAlpha removeColor ratio (SIMD on/off) 0.476x (52.4% faster)

ParparVM vs HotSpot (JDK 25): Windows arm64

Runner CPU: ARMv8 (64-bit) Family 8 Model D49 Revision 0, MICROSOFT CORPORATION (baseline windows-arm64@armv8-64-bit-family-8-model-d49-microsoft-corporation)

Ratios are ParparVM / JDK 25: below 1.00x ParparVM is faster (time) or smaller (RAM). Median of 5 interleaved, paired rounds; every run's output was verified. A ratio more than 20% (time) / 25% (RAM) above its baseline in vm/selfhost/perf-baseline/ is a regression and fails; one that far below is an improvement, reported but not failed (a row whose calibration runs were noisier carries a wider tolerance), and for RAM the change must also exceed 0.05x in absolute terms. Both run unpinned on all of the runner's CPUs, with their own default thread counts.

Benchmark Cores Time RAM Status
hello (WinHelloMain) 4 1.42x (base 1.45x, -2.1%) 0.78x (base 0.75x, +4.4%) ok
translator (self) 4 0.93x (base 0.84x, +10.6%) 0.49x (base 0.51x, -3.9%) ok
intArithmetic 4 1.04x (base 1.04x, -0.1%) 0.06x (base 0.06x, +3.2%) ok
longArithmetic 4 0.79x (base 0.80x, -0.1%) 0.06x (base 0.06x, +3.7%) ok
mathTranscendental 4 0.73x (base 0.72x, +1.8%) 0.07x (base 0.06x, +1.8%) ok
arraySequential 4 0.39x (base 0.46x, -15.1%) 0.39x (base 0.39x, +0.1%) ok
arrayRandom 4 0.93x (base 0.94x, -0.6%) 0.23x (base 0.23x, +0.5%) ok
objectAllocation 4 1.82x (base 1.82x, -0.0%) 0.41x (base 0.43x, -5.7%) ok
valueEscape 4 0.76x (base 0.76x, +0.1%) 0.05x (base 0.05x, +3.9%) ok
hashMapChurn 4 0.99x (base 0.98x, +0.7%) 0.12x (base 0.12x, -2.7%) ok
stringBuilding 4 1.54x (base 1.43x, +7.7%) 0.27x (base 0.27x, -0.5%) ok
recursion 4 1.42x (base 1.46x, -2.8%) 0.07x (base 0.07x, +1.3%) ok
quicksort 4 1.01x (base 1.00x, +0.7%) 0.12x (base 0.12x, +0.7%) ok

Result: no regression

shai-almog and others added 2 commits November 15, 2026 07:21
The browser leg renders through a software GPU; a GpuPostDepth frame takes
seconds and holds the main thread, so the three frames the gate waits for
never fit the 10s HTML5 budget and the test timed out with no capture.

Co-Authored-By: Claude Opus 5.5 <noreply@anthropic.com>
@shai-almog

shai-almog commented Nov 15, 2026 •

Copy link
Copy Markdown
Collaborator Author

Compared 265 screenshots: 265 matched.
✅ JavaScript-port screenshot tests passed.

@shai-almog

shai-almog commented Nov 15, 2026 •

Copy link
Copy Markdown
Collaborator Author

Compared 212 screenshots: 212 matched.
✅ Native Mac screenshot tests passed.

Benchmark Results

  • VM Translation Time: 0 seconds
  • Compilation Time: 864 seconds

Detailed Performance Metrics

Metric Duration
SIMD kernel backend SSE2 (x64) / NEON (arm64) native kernels
SIMD int-add (64K x300) java 67ms / native 7ms = 9.5x speedup
SIMD float-mul (64K x300) java 61ms / native 3ms = 20.3x speedup
SIMD kernel correctness PASS (native result == scalar reference)
Base64 payload size 8192 bytes
Base64 benchmark iterations 6000
Base64 SIMD byte path active (NEON-accelerated)
Base64 CN1 encode 51.000 ms
Base64 CN1 decode 74.000 ms
Base64 native encode 890.000 ms
Base64 encode ratio (CN1/native) 0.057x (94.3% faster)
Base64 native decode 338.000 ms
Base64 decode ratio (CN1/native) 0.219x (78.1% faster)
Base64 SIMD encode 61.000 ms
Base64 encode ratio (SIMD/CN1) 1.196x (19.6% slower)
Base64 SIMD decode 54.000 ms
Base64 decode ratio (SIMD/CN1) 0.730x (27.0% faster)
Base64 encode ratio (SIMD/native) 0.069x (93.1% faster)
Base64 decode ratio (SIMD/native) 0.160x (84.0% faster)
Image encode benchmark iterations 100
Image createMask (SIMD off) 10.000 ms
Image createMask (SIMD on) 3.000 ms
Image createMask ratio (SIMD on/off) 0.300x (70.0% faster)
Image applyMask (SIMD off) 53.000 ms
Image applyMask (SIMD on) 55.000 ms
Image applyMask ratio (SIMD on/off) 1.038x (3.8% slower)
Image modifyAlpha (SIMD off) 67.000 ms
Image modifyAlpha (SIMD on) 56.000 ms
Image modifyAlpha ratio (SIMD on/off) 0.836x (16.4% faster)
Image modifyAlpha removeColor (SIMD off) 78.000 ms
Image modifyAlpha removeColor (SIMD on) 93.000 ms
Image modifyAlpha removeColor ratio (SIMD on/off) 1.192x (19.2% slower)

@shai-almog

shai-almog commented Nov 15, 2026 •

Copy link
Copy Markdown
Collaborator Author

Compared 230 screenshots: 230 matched.
Native Linux port (x64), GTK3/Cairo/Pango, ParparVM bytecode-to-C (no JVM): the hellocodenameone screenshot suite rendered by a native ELF built + run on the GitHub x64 runner. Baseline: scripts/linux/screenshots.

ParparVM vs HotSpot (JDK 25): Linux x64

Runner CPU: AMD EPYC 9V74 80-Core Processor (baseline linux-x64@amd-epyc-9v74-80-core-processor)

Ratios are ParparVM / JDK 25: below 1.00x ParparVM is faster (time) or smaller (RAM). Median of 5 interleaved, paired rounds; every run's output was verified. A ratio more than 20% (time) / 25% (RAM) above its baseline in vm/selfhost/perf-baseline/ is a regression and fails; one that far below is an improvement, reported but not failed (a row whose calibration runs were noisier carries a wider tolerance), and for RAM the change must also exceed 0.05x in absolute terms. Both run unpinned on all of the runner's CPUs, with their own default thread counts.

Benchmark Cores Time RAM Status
hello (LinuxHelloMain) 4 1.13x (base 0.90x, +26.2%) 0.83x (base 0.96x, -13.5%) ok
translator (self) 4 0.63x (base 0.63x, +0.6%) 0.52x (base 0.46x, +12.0%) ok
intArithmetic 4 1.10x (base 1.10x, -0.0%) 0.04x (base 0.06x, -31.4%) ok
longArithmetic 4 1.08x (base 1.08x, +0.0%) 0.04x (base 0.06x, -30.8%) ok
mathTranscendental 4 1.10x (base 1.09x, +0.2%) 0.04x (base 0.07x, -40.0%) ok
arraySequential 4 2.76x (base 2.81x, -1.6%) 0.36x (base 0.35x, +1.4%) ok
arrayRandom 4 1.01x (base 1.02x, -0.9%) 0.20x (base 0.21x, -4.6%) ok
objectAllocation 4 1.31x (base 1.21x, +9.0%) 0.29x (base 0.39x, -25.0%) ok
valueEscape 4 0.10x (base 0.10x, -0.0%) 0.03x (base 0.06x, -41.6%) ok
hashMapChurn 4 1.18x (base 1.10x, +8.0%) 0.10x (base 0.10x, +3.0%) ok
stringBuilding 4 1.33x (base 1.49x, -10.6%) 0.26x (base 0.26x, +0.4%) ok
recursion 4 1.34x (base 1.24x, +7.4%) 0.04x (base 0.06x, -29.5%) ok
quicksort 4 1.08x (base 1.07x, +1.2%) 0.10x (base 0.11x, -11.7%) ok

Result: no regression

@shai-almog

shai-almog commented Nov 15, 2026 •

Copy link
Copy Markdown
Collaborator Author

Compared 230 screenshots: 230 matched.
Native Linux port (arm64), GTK3/Cairo/Pango, ParparVM bytecode-to-C (no JVM): the hellocodenameone screenshot suite rendered by a native ELF built + run on the GitHub arm64 runner. Baseline: scripts/linux/screenshots-arm.

ParparVM vs HotSpot (JDK 25): Linux arm64

Runner CPU: Neoverse-N2 (baseline linux-arm64@neoverse-n2)

Ratios are ParparVM / JDK 25: below 1.00x ParparVM is faster (time) or smaller (RAM). Median of 5 interleaved, paired rounds; every run's output was verified. A ratio more than 20% (time) / 25% (RAM) above its baseline in vm/selfhost/perf-baseline/ is a regression and fails; one that far below is an improvement, reported but not failed (a row whose calibration runs were noisier carries a wider tolerance), and for RAM the change must also exceed 0.05x in absolute terms. Both run unpinned on all of the runner's CPUs, with their own default thread counts.

Benchmark Cores Time RAM Status
hello (LinuxHelloMain) 4 1.15x (base 1.02x, +12.5%) 0.78x (base 0.66x, +18.4%) ok
translator (self) 4 0.79x (base 0.70x, +12.6%) 0.46x (base 0.43x, +5.9%) ok
intArithmetic 4 1.04x (base 1.04x, -0.1%) 0.03x (base 0.03x, +4.4%) ok
longArithmetic 4 0.79x (base 0.79x, -0.0%) 0.03x (base 0.03x, +5.0%) ok
mathTranscendental 4 1.09x (base 1.10x, -0.3%) 0.04x (base 0.03x, +9.1%) ok
arraySequential 4 0.35x (base 0.36x, -2.4%) 0.37x (base 0.37x, +0.4%) ok
arrayRandom 4 0.94x (base 0.94x, +0.8%) 0.20x (base 0.20x, +0.6%) ok
objectAllocation 4 2.02x (base 1.77x, +14.1%) 0.40x (base 0.37x, +8.8%) ok
valueEscape 4 0.51x (base 0.51x, -0.1%) 0.03x (base 0.03x, +5.9%) ok
hashMapChurn 4 0.87x (base 0.84x, +3.4%) 0.12x (base 0.12x, -2.1%) ok
stringBuilding 4 1.45x (base 1.57x, -7.6%) 0.32x (base 0.26x, +20.4%) ok
recursion 4 1.44x (base 1.43x, +0.3%) 0.04x (base 0.04x, +3.4%) ok
quicksort 4 1.00x (base 0.99x, +0.4%) 0.09x (base 0.09x, +1.3%) ok

Result: no regression

@shai-almog

shai-almog commented Nov 15, 2026 •

Copy link
Copy Markdown
Collaborator Author

Compared 213 screenshots: 213 matched.
✅ Native iOS Metal screenshot tests passed.

Benchmark Results

  • VM Translation Time: 0 seconds
  • Compilation Time: 3596 seconds

Build and Run Timing

Metric Duration
Simulator Boot 167000 ms
Simulator Boot (Run) 2000 ms
App Install 14000 ms
App Launch 1000 ms
Test Execution 486000 ms

Detailed Performance Metrics

Metric Duration
SIMD kernel backend SSE2 (x64) / NEON (arm64) native kernels
SIMD int-add (64K x300) java 125ms / native 5ms = 25.0x speedup
SIMD float-mul (64K x300) java 78ms / native 4ms = 19.5x speedup
SIMD kernel correctness PASS (native result == scalar reference)
Base64 payload size 8192 bytes
Base64 benchmark iterations 6000
Base64 SIMD byte path active (NEON-accelerated)
Base64 CN1 encode 86.000 ms
Base64 CN1 decode 87.000 ms
Base64 native encode 1187.000 ms
Base64 encode ratio (CN1/native) 0.072x (92.8% faster)
Base64 native decode 924.000 ms
Base64 decode ratio (CN1/native) 0.094x (90.6% faster)
Base64 SIMD encode 81.000 ms
Base64 encode ratio (SIMD/CN1) 0.942x (5.8% faster)
Base64 SIMD decode 50.000 ms
Base64 decode ratio (SIMD/CN1) 0.575x (42.5% faster)
Base64 encode ratio (SIMD/native) 0.068x (93.2% faster)
Base64 decode ratio (SIMD/native) 0.054x (94.6% faster)
Image encode benchmark iterations 100
Image createMask (SIMD off) 6.000 ms
Image createMask (SIMD on) 1.000 ms
Image createMask ratio (SIMD on/off) 0.167x (83.3% faster)
Image applyMask (SIMD off) 259.000 ms
Image applyMask (SIMD on) 31.000 ms
Image applyMask ratio (SIMD on/off) 0.120x (88.0% faster)
Image modifyAlpha (SIMD off) 58.000 ms
Image modifyAlpha (SIMD on) 62.000 ms
Image modifyAlpha ratio (SIMD on/off) 1.069x (6.9% slower)
Image modifyAlpha removeColor (SIMD off) 46.000 ms
Image modifyAlpha removeColor (SIMD on) 29.000 ms
Image modifyAlpha removeColor ratio (SIMD on/off) 0.630x (37.0% faster)

@shai-almog

shai-almog commented Nov 15, 2026 •

Copy link
Copy Markdown
Collaborator Author

Compared 253 screenshots: 253 matched.
✅ Native Apple Watch (watchOS, Core Graphics) screenshot tests passed.

@shai-almog
shai-almog merged commit 043b63b into master Nov 15, 2026
40 of 89 checks passed
@shai-almog
shai-almog deleted the gpu-shader-nodes branch November 15, 2026 12:52
shai-almog added a commit that referenced this pull request Nov 16, 2026
#6232 added the test without a tvOS reference, so the tvOS suite fails
on every PR with missing_expected. Captured from this PR's tvOS run.

Co-Authored-By: Claude Opus 5.5 <noreply@anthropic.com>
shai-almog added a commit that referenced this pull request Nov 16, 2026
…agent tooling (#6242)

* Foldable skins: 3D fold simulation, lockstep recording, designer and agent tooling

- Simulator: foldable skins (book, flip, dual screen) with a cover display,
  drawn in 3D with com.codename1.gpu and animated between postures; 3D
  device rotation.
- Recording: lockstep capture pins an animation clock per frame, so
  scripted fold/rotation clips are smooth at 60 fps on any machine;
  Simulate -> Record Device Tour; hidden (windowless) simulator for agents
  (CN1_SIMULATOR_HIDDEN, cn1.agent.hidden).
- Skin Designer: foldable/duo authoring, physical frame units, a fixed
  corner mask (no outline), cover image as the folded half of the body.
- devices.json: curated foldables and Surface Duo data.
- Agent skill: promo videos and skins reference, SkinTool.java.

Co-Authored-By: Claude Opus 5.5 <noreply@anthropic.com>

* Fix CI: copyright header, Vale adverb, hide the fold button on non-foldable skins

The javase screenshot baseline caught a greyed fold button on every
ordinary skin; the button is now shown only for a foldable skin.

Co-Authored-By: Claude Opus 5.5 <noreply@anthropic.com>

* tvOS: add the GpuShaderHarbour golden master never got

#6232 added the test without a tvOS reference, so the tvOS suite fails
on every PR with missing_expected. Captured from this PR's tvOS run.

Co-Authored-By: Claude Opus 5.5 <noreply@anthropic.com>

---------

Co-authored-by: Claude Opus 5.5 <noreply@anthropic.com>
shai-almog added a commit that referenced this pull request Nov 17, 2026
Taking master's side of the GPU files after #6232 landed lost turf(),
canopy() and the instance-colour fixes this branch had added on top, so
rbx-view no longer compiled.

Co-Authored-By: Claude Opus 5.5 <noreply@anthropic.com>
Sign up for free to join this conversation on GitHub. Already have an account? Sign in to comment

Labels

None yet

Projects

None yet

Development

Successfully merging this pull request may close these issues.

1 participant